A finance lead opens your app on a Thursday afternoon and clicks “Generate quarterly board report.” The spinner starts. Forty seconds later it is still spinning, so she switches to her inbox. Ten minutes after that, her laptop goes to sleep while she is in a meeting. When she comes back, the tab has reloaded, the spinner is gone, and there is no report anywhere in the app. Her account shows 18 credits spent.
She clicks the button again, pays twice, and files a support ticket. Your on-call engineer finds a canceled request in the logs and nothing that says how far the job got.
If your team ships AI features that take longer than a page load, this is probably already happening in your product.
Why long AI features break
Most AI features start life as a request handler: the browser sends a POST, the server calls a model a few times, and streams tokens back. It works in a demo because nobody closes the tab.
In production, a long-running request depends on several things staying alive at once:
- The browser tab, which users close, reload, or let the OS suspend.
- The network path, including proxies and load balancers that enforce idle and total timeouts.
- The server process, which gets restarted by deploys, autoscaling, and out-of-memory kills.
- The model provider, which rate-limits, times out, or returns errors under load.
When any one of these fails, the work tied to that request fails with it. The root cause is simple: the lifetime of the job is coupled to the lifetime of the connection. A six-step report should not depend on whether a laptop lid is open.
There is also a cost dimension. Every model call costs tokens, often passed to customers as credits. When a job dies at step five of six, the first four steps were paid for and thrown away, and the retry pays for them again.
Why the usual workarounds fall short
Longer timeouts. Raising the load balancer and server timeouts buys time but does nothing for closed tabs, sleeping laptops, or rolling deploys.
A background job queue. Moving work to a task queue worker is a real improvement, because the job no longer depends on the browser. But most queues treat a job as one opaque unit. If the worker crashes halfway through drafting 50 personalized emails, the queue either retries the whole job from scratch or gives up. Progress lives in local variables that vanish with the process.
Hand-rolled checkpoints. Some teams add a status table and write progress after each step. This works until you need per-step retries, cancellation, fan-out failures, and code changes while jobs are in flight. Then you are building a workflow engine by accident.
The general approach: decouple the request from the execution
The pattern that holds up is to treat every long AI feature as a durable job with its own identity, separate from any HTTP request:
- Return a job ID immediately. The “Generate” button starts a job and gets back an ID in milliseconds. The UI shows the job’s state, not a held-open connection.
- Make “start job” idempotent. Derive a job key from the tenant, user, feature, and inputs (for example, tenant plus report type plus quarter). If a job with that key is already running or finished, return the existing ID instead of starting another. Double clicks and retries stop costing money.
- Break the work into recorded steps. Each model call, data query, or file write is a step whose result is saved once it completes. After a crash, the job resumes from the last completed step instead of from the beginning.
- Push progress instead of holding the connection open. Each step emits a progress event (“3 of 6 sections drafted”) onto a pub/sub topic, and a websocket or server-sent events gateway relays it to whichever browser tab is open for that job.
- Notify on completion. When the job finishes, send an in-app notification or email with a link.
- Support cancellation as an event. A “Cancel” button sends an external event to the running job. The job checks for it between steps and stops cleanly.
- Enforce per-tenant fairness. Limit concurrent jobs per tenant and apply rate limits to model calls so one large customer running a workspace-wide agent does not starve everyone else.
This is durable execution in practice: progress is persisted as the job runs, so failures become pauses rather than losses.
Implementing it with a workflow engine
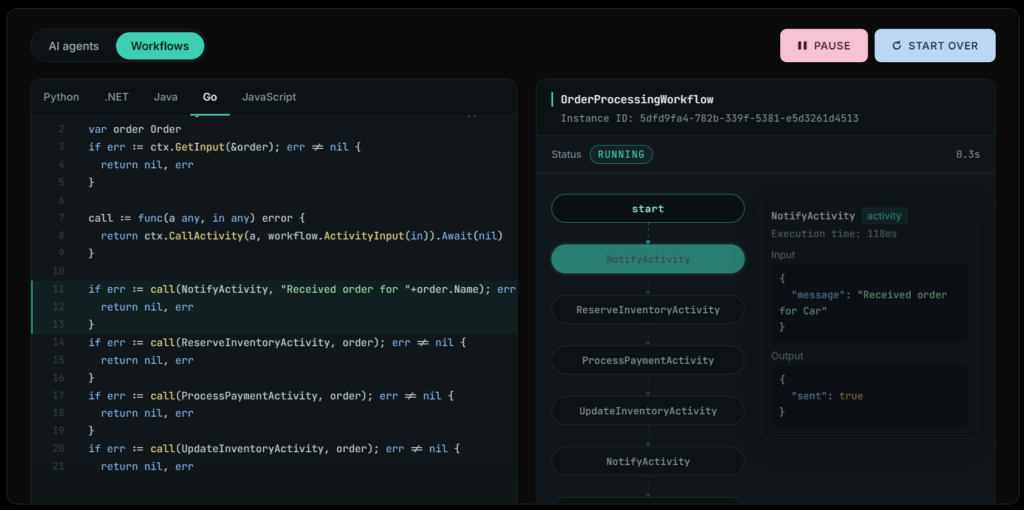
You can build these principles on several workflow engines. One open-source option is Dapr, a CNCF graduated project that runs as a sidecar next to your service on Kubernetes, VMs, or self-hosted machines. Its workflow building block lets you write the job as ordinary code, while the runtime keeps an event-sourced history in a state store. After a crash, the workflow replays from that history, and activities that already completed are not executed again.
Here is a sketch of the board report job using the Dapr Python SDK. Drafting sections fans out in parallel, and model-calling steps get a retry policy.
import dapr.ext.workflow as wf
from datetime import timedelta
wfr = wf.Workfloe()
retry = wf.RetryPolicy(first_retry_interval=timedelta(seconds=2), max_number_of_attempts=5, backoff_coefficient=2, max_retry_interval=timedelta(minutes=1))
@wfr.workflow(name=”board_report”)
def board_report(ctx: wf.DaprWorkflowContext, job: dict):
sections = yield ctx.call_activity(planwRuntim_sections, input=job, retry_policy=retry)
drafts = yield wf.when_all([ctx.call_activity(draft_section, input=s, retry_policy=retry) for s in sections])
yield ctx.call_activity(save_report, input={“job”: job, “drafts”: drafts}, retry_policy=retry)
@wfr.activity(name=”draft_section”)
def draft_section(ctx: wf.WorkflowActivityContext, section: dict): …
Use the job key as the workflow instance ID. If your start endpoint uses the deterministic job key as the instance ID and checks for an existing instance first, duplicate clicks resolve to the same workflow. Test your engine’s exact behavior when an ID already exists.
Keep the orchestrator deterministic. Dapr Workflow requires orchestrator code to be deterministic, with all I/O inside activities. Model calls, database reads, and progress publishing belong in activities.
Publish progress from activities. Each activity can publish a small event through Dapr pub/sub, which supports brokers such as Kafka, RabbitMQ, and Redis and delivers at least once. Your websocket gateway subscribes and forwards events to the right tenant and job. Make the UI tolerate duplicate messages.
Model cancellation and approvals as external events. A workflow can wait for an external event, such as “cancel” or “approve send,” and race it against a durable timer with when_any. This suits bulk email drafting, where a human reviews before anything is sent.
Put limits on the edges. Dapr resiliency policies can apply timeouts, retries, and circuit breakers to calls that go through Dapr, such as service invocation or components like the conversation API. Per-tenant concurrency is usually something you enforce at the start endpoint, by counting running jobs for that tenant before scheduling a new one, or by queuing the start request.
If your AI feature is an agent built with a framework like LangGraph, the OpenAI Agents SDK, or Pydantic AI, you do not have to rewrite it as hand-coded activities. Dapr Agents, an open-source Python framework in the Dapr project, builds agents directly on Dapr Workflow. For existing frameworks, Diagrid, a company started by Dapr’s creators, is one provider that offers integrations through its diagrid Python package, where agent steps such as tool calls run as durable activities, with the granularity depending on the framework. As with any vendor, verify that the integration covers your framework version and run a kill-the-worker test in your own environment before relying on it.
Choosing where to run it
You can run Dapr yourself on Kubernetes, enable it as a managed integration in Azure Container Apps, or use a managed runtime. Self-hosting gives full control and full operational responsibility, including the state store that holds workflow history. If your team would rather not operate the runtime, a hosted platform offering durable execution for AI agents and workflows is one route to evaluate alongside running open-source Dapr yourself. Either way, keep your workflow code on open APIs so the decision stays reversible.
A rollout checklist
Start with the AI feature that wastes the most credits:
- ☐ Replace the long request with a “start job” endpoint that returns a job ID.
- ☐ Derive an idempotency key per job and reuse existing jobs for duplicate starts.
- ☐ Split the job into steps where each model call or write is a recorded activity.
- ☐ Add retry policies with backoff to activities that call model providers.
- ☐ Publish progress events per step and relay them to the UI over websockets or SSE.
- ☐ Render job state from the server on page load, so a reloaded tab picks up where it left off.
- ☐ Send a notification with a link when the job completes or fails.
- ☐ Wire a “Cancel” button to an external event the workflow checks between steps.
- ☐ Enforce per-tenant concurrency limits at the start endpoint.
- ☐ Only charge credits for steps that actually complete, and never for replays.
- ☐ Test failure on purpose: close the tab, kill the worker mid-job, deploy during a run, and confirm the job finishes and bills once.
Conclusion
The finance lead did nothing wrong. She closed a tab and let her laptop sleep. The failure belonged to an architecture that tied an expensive job to a fragile connection.
Decoupling the request from the execution fixes that. Give each job an identity, record each step, push progress instead of holding a socket, and make starts and charges idempotent. Whether you build it on Dapr, another workflow engine, or a managed platform, the result your users notice is the same: they click “Generate,” walk away, and come back to a finished report and a fair bill.